Background
As an ocassional geocacher and geohasher, I'm encouraged to post logs describing my adventures, and each major provider wants me to post my logs into their silo (see e.g. my logs on geocaching.com, on opencache.uk, and on the geohashing wiki). But as a believer in the ideals behind the IndieWeb (since long before anybody said "IndieWeb"), I'm opposed to keeping the only copy of content that I produce in an environment controlled by somebody else (why?).
How do I reconcile this?
Alt
Wrist-mounted GPS in the snow.
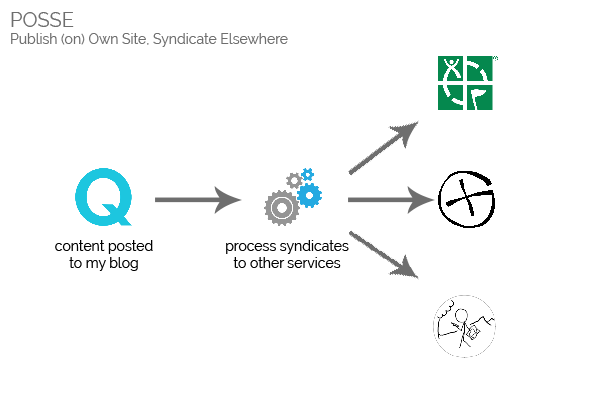
What I'd prefer would be to be able to write my logs here, on my own blog, and for my content to by syndicated via some process into the logging systems of the various silo sites I prefer. This approach is called POSSE - Publish on Own Site, Syndicate Elsewhere. In addition to the widely-described benefits of this syndication strategy, such a system would also make it possible for me to:
- write single posts amalgamating multiple locations (e.g. a geohashing expedition that included geocache finds) or,
- write single posts that represent the same location published on multiple silos (e.g. a visit to a geocache published on two different listing sites [e.g. 1, 2])
Applying such an tool would require some work as different silos have different acceptable content rules (geocaching.com, for example, effectively forbids mention of the existence of other geocache listing sites), but that'd theoretically be workable.
Alt
POSSE would involve posts being made first to my blog and then converted via some process into logs in each relevant silo
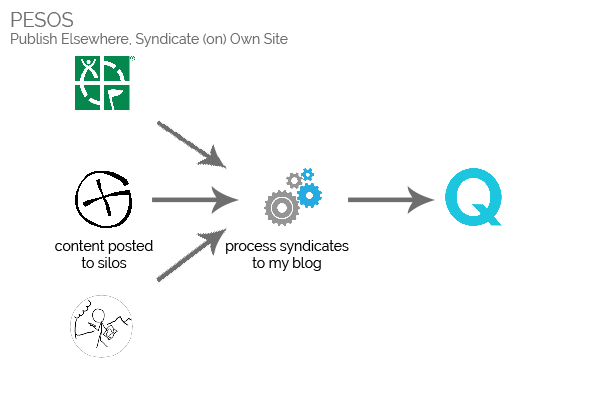
Unfortunately, content rules aren't the only factor making PESOS - writing content into each silo and then copying it to my blog - preferable to POSSE. There's also:
- Not all of the silos offer suitable (published) APIs, and where they do, the APIs are all distinctly different.
- Geocaching.com specifically forbids the use of unapproved automated robots to access the site (and almost certainly wouldn't approve the kind of tool that would be ideal).
- The siloed services are well-supported by official and third-party apps with medium-specific logic which make them the best existing way to produce logs.
Alt
PESOS would mean that posts were made "the usual way" to the silos and then a process duplicates them onto my blog
Needless to say: as much as I'd have loved to POSSE my geo* logs, PESOS will do.
Implementation
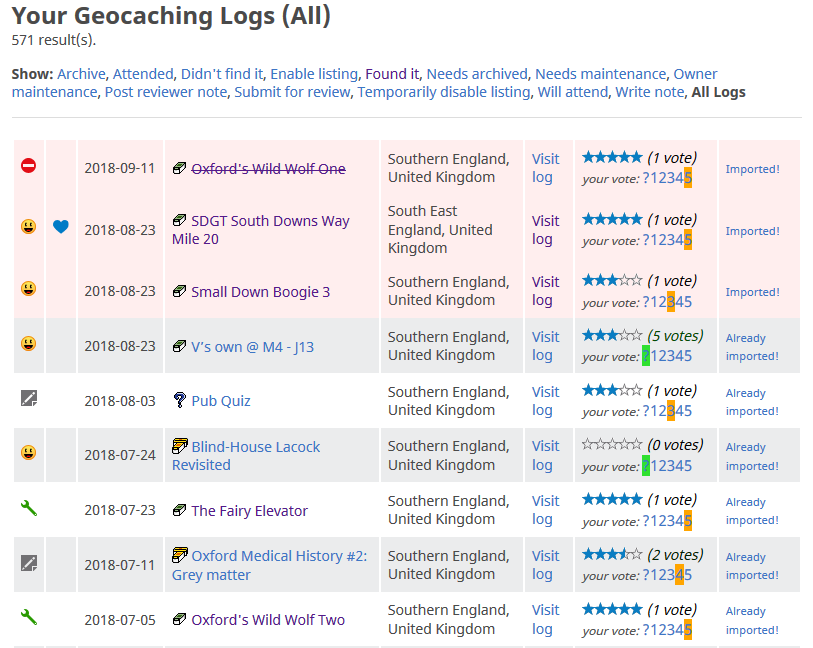
My implementation is a WordPress plugin which does two things. The first is that it provides a Javascript bookmarklet and an accompanying dynamically-generated Javascript file (the former loads the latter) served from my blog's domain. That Javascript file contains reference to every log already published to my blog, so that the Javascript code can deliberately omit these logs from any import. When executed on a log listing page like those linked above, it copies all of the details of that log into a form which submits them back to my blog, where it's received by the second part of the plugin.
Alt
Geocache logs to WordPress importer seen running on geocaching.com
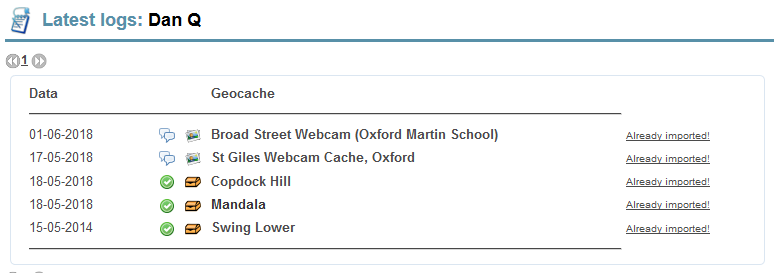
The second part of the plugin takes this data and creates a new draft post. My plugin is pretty opinionated on this part because it's geared strongly towards my use-case, so if you want to use it yourself you'll probably want to tweak the code a little (e.g. it applies specific tags and names metadata fields a particular way).
Alt
Import plugin running on OpenCache.uk
It's not fully-automated and it's not POSSE,but it's "good enough" and it's enabled me to synchronise all of my cache logs to my blog. I've plans to extend it to support other GPS game services to streamline my de-siloisation even further.
And of course, I've open-sourced the whole thing. If it's any use to you (probably in an adapted form), it's all yours.
My friend Beverley highlights an important fact about learning to develop your skills as a software engineer: that it’s only fun if you make it fun. Side-projects, whether useful or silly, are an opportunity to expand your horizons from the comfort of your own home.
Read more →
This Article was mentioned on danq.me
Read more →
This Article was mentioned on polytechnic.co.uk
Read more →
This weekend, I attended part of Oxford’s first ever IndieWebCamp! As a long (long, long) time proponent of IndieWeb philosophy (since long before anybody said “IndieWeb”, at least) I’ve got my personal web presence pretty-well sorted out. Still, I loved the idea of attending and pushing some of my own tools even further: after all, a personal website isn’t “finished” until its owner says it is! One of the things I ended up hacking on was pretty-predictable: enhancements to my recently-open-sourced geocaching PESOS tools… but the other’s worth sharing too, I think.
Some of IndieWebCamp Oxford’s attendees share knowledge and hack code together.I’ve recently been playing with WebVR – for my day job at the Bodleian, I swear! – and I was looking for an excuse to try to expand some of what I’d learned into my personal blog, too. Given that I’ve recently acquired a Ricoh Theta V I thought that this’d be the perfect opportunity to add WebVR-powered panoramas to this site. My goals were:
Entirely self-hosted; no external third-party dependencies
Must degrade gracefully (i.e. even if you’re using an older browser, don’t have Javascript enabled, etc.) it should at least show the original image
In plain-old browsers should support mouse (or touch) control to pan the scene
Where accelerators are available (e.g. mobiles), “magic window” support to allow twist-to-explore
And where “true” VR hardware (Cardboard, Vive, Rift etc.) with WebVR support is available, allow one-click use of that
It wouldn’t be a geeky hacky camp thingy if it didn’t finish at a bar.Hopefully the images above are working for you and are “interactive”. Try click-and-dragging on them (or tilt your device), try fullscreen mode, and/or try WebVR mode if you’ve got hardware that supports it. The mechanism of operation is slightly hacky but pretty simple: here’s how it works:
The image is inserted into the page as normal but with an extra CSS class of “vr360” and a data attribute pointing to the full-resolution image, e.g.:
<img class="vr360"
                    src="/uploads/2018/09/R0010005_20180922182210-1024x512.jpg" alt="IndieWebCamp Oxford attendees at the pub" width="640" height="320"
                    data-vr360="/uploads/2018/09/R0010005_20180922182210.jpg" />
Some Javascript swaps-out images with this class for an iframe of the same size, showing a special page and passing the image filename after the hash, e.g.:
for(vr360 of document.querySelectorAll('.vr360')){const width = parseInt(vr360.width);
const height = parseInt(vr360.height);
if(width == 0) width = '100%'; // Fallback for where width/height not specified,
if(height == 0) height = '100%'; // needed because of some quirks with Dan's lazy-loader
vr360.outerHTML = `<iframe src="/q26-content/themes/q18/vr360/#${vr360.dataset.vr360}" width="${width}" height="${height}" class="aligncenter" class="vr360-frame" style="min-width: 340px; min-height: 340px;"></iframe>`;
}
The iframe page loads this Javascript file. This loads three.js (to make 3D things easy) and WebVR-polyfill (to fix browser quirks). Finally (scroll to the bottom of the code), it creates a camera in the centre of a sphere, loads the image specified in the hash, flips it, and paints it onto the inside surface of the sphere, sets up controls, and turns the user loose on it. That’s all there is to it!
You’re welcome to any of my code if you’d like a drop-in approach to hosting panoramic photographs on your own personal site. My solution’s pretty extensible if you want e.g. interactive hotspots or contextual overlays – in fact, that – plus an easy route to editing the content for less-technical users – is pretty-much exactly what I’m working on for my day job at the moment.
Read more →
Personal website and blog of Dan Q: life, technology, magic, games, the Web, relationships, and more.
Read more →